 1 hour ago
1
xAI has a new coding model, and it arrived with a scoreboard. Grok 4.7, launched on September 21, 2026, now holds first, second and third place on the VulcanBench Frontier v4 leaderboard. Three effort levels, three podium spots Grok 4.7 lets users pick how much reasoning effort the model spends on a task. Each setting was scored separately on VulcanBench Frontier v4, and each landed near the top. At the extra-high effort level, Grok 4.7 scored 93.15, good for first place. The high effort setting followed at 92.71 in second, and the medium setting took third with 92.30. The closest rival named in the results was Claude Fable 5.1, which scored 91.84. That puts even Grok 4.7’s medium setting ahead of it on this particular test. The standout result came at extra-high effort. There, Grok 4.7 passed all 23 behavioral-reconstruction tasks on the benchmark, with strong code quality scores under the latest testing protocol. A behavioral-reconstruction task asks a model to rebuild software so that it behaves exactly like an existing reference. Getting the output roughly right does not count, because the code has to match what the original actually does. What VulcanBench actually measures Vul...
Related
Paxos-issued USDG hits $3.2 billion market cap after 340% ye...
19 minutes ago
0
THORChain co-founder says acting against Bitget hacker was p...
23 minutes ago
0
Strike launches 3.6% interest on cash, paid out in Bitcoin
28 minutes ago
0
Ex-AI lab researchers tell NYC Council humans are checking A...
29 minutes ago
0
Solana price prediction: Can SOL hit $150 in October?
29 minutes ago
0
Ether.fi taps Ethena to launch its own US dollar stablecoin
31 minutes ago
0
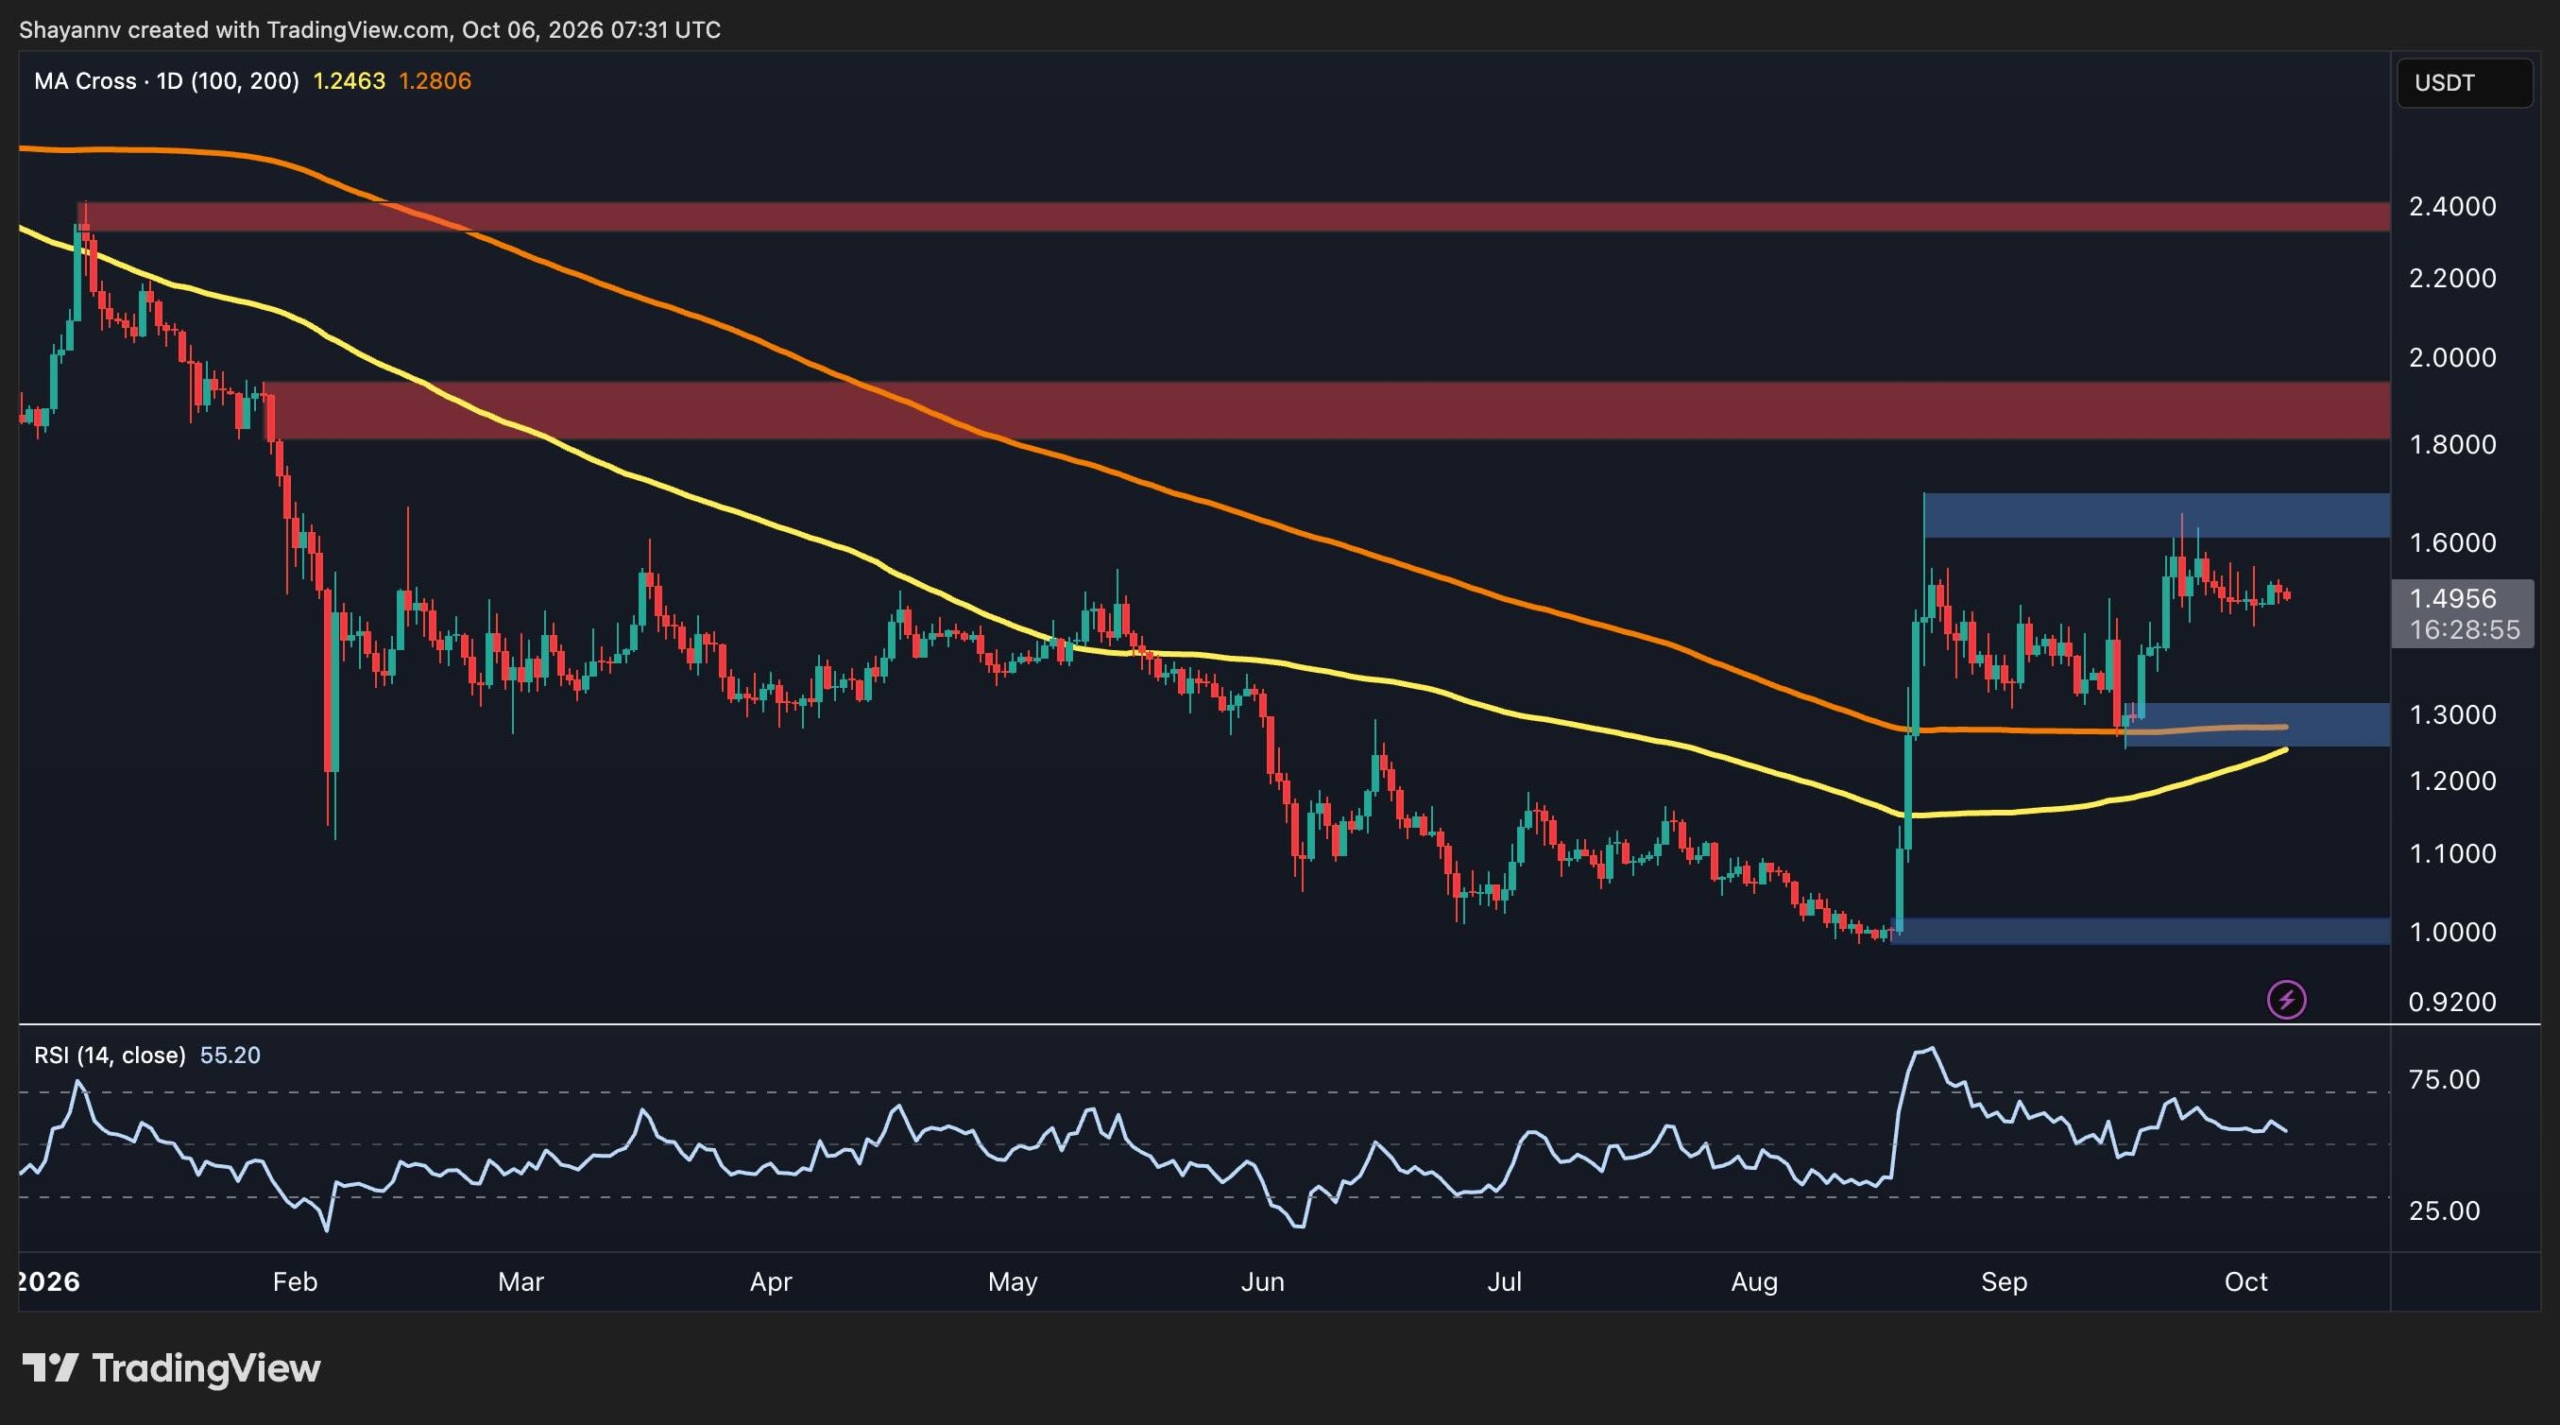
Ripple Price Analysis: Is XRP Consolidation Almost Over as t...
31 minutes ago
0
Ampersand raises $15M to connect AI agents with legacy enter...
35 minutes ago
0
Popular

Starknet shields 45 assets with new privacy framework
4 weeks ago
100


Chainflip loses 736,442 USDT in TRON exploit
3 weeks ago
42
 English (US) ·
© Clint's Cryto News 2026. All rights are reserved
