Perplexity AI has a new contextual embedding model, pplx-embed-v2-context-9b-preview, and the company says it sets a new state-of-the-art for document retrieval. The trick is simple to describe and hard to pull off. The model encodes an entire document once, so every piece of it carries the context of the whole. What the new model actually does The problem is chunking. Long documents get sliced into smaller pieces before they are embedded, and those pieces often lose the plot. A chunk that says “the company raised its forecast” is useless if the model has forgotten which company the document was about. Traditional approaches embed each chunk in isolation, like reading one page torn out of a novel. Perplexity’s contextual approach tries to fix that. By processing the full document in one pass, the model lets each chunk inherit information from the surrounding text. The model carries a “preview” tag, which signals it is an early release rather than a finished product. Perplexity is positioning it as the next step after its first generation of contextual models. The v1 benchmark bar it has to clear On February 26, 2026, the company released two embedding families: pplx-embed-v1 and pp...
Perplexity’s new contextual embedding model claims top spot in document retrieval
 3 hours ago
2
Related
Bitcoin nears green September close as bulls look to October...
32 minutes ago
0
California billionaire tax proposal gains attention ahead of...
40 minutes ago
0
ESMA Calls for Advertising Rules on Crypto Influencers: Six ...
41 minutes ago
0
FTC investigates OpenAI, Anthropic over AI safety concerns: ...
42 minutes ago
0
Ethereum Glamsterdam: On October 6 Sepolia Forks, Not the Ma...
49 minutes ago
0
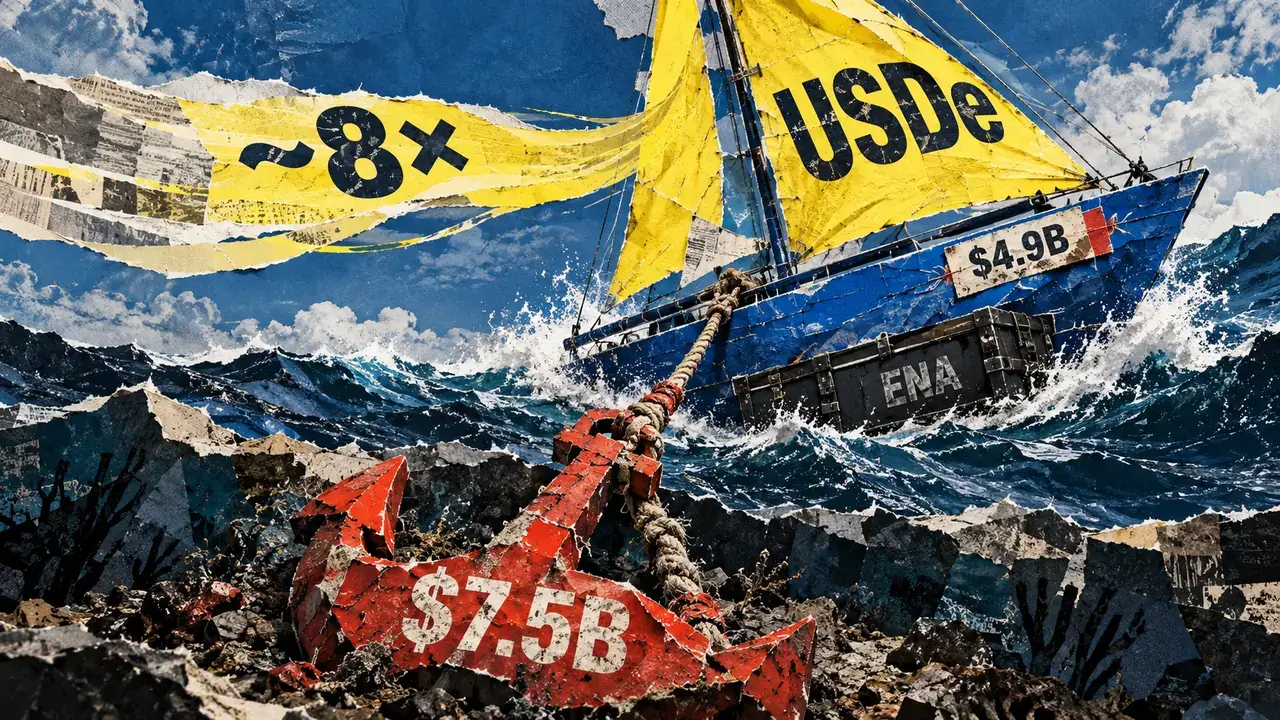
Standard Chartered says Ethena’s ENA could crush Bitcoin and...
51 minutes ago
0
Pokemon Collector $55 Million Crypto Exploit Trial Opens In ...
51 minutes ago
0
$766 Million Lost to Crypto Hacks in One Month: What It Mean...
57 minutes ago
3
Popular

Starknet shields 45 assets with new privacy framework
3 weeks ago
96

SpaceX returns to $2T valuation after IPO volatility
3 weeks ago
48
Stablecoins could enter M1 or M2, Fed study says
3 weeks ago
44
Binance launches PONS and Hajimi perpetual futures
3 weeks ago
44
 English (US) ·
© Clint's Cryto News 2026. All rights are reserved
